Boing Boing: Stick Michelangelo’s “David” on your blog to protest censorware
Here I am, sticking it. err… I think that came out wrong.
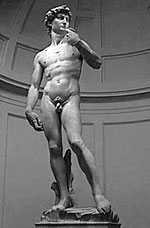 Obviously pornography here. Not art at all. Sick bastard that Michelangelo.
Boing Boing: Stick Michelangelo’s “David” on your blog to protest censorware
Here I am, sticking it. err… I think that came out wrong.
Obviously pornography here. Not art at all. Sick bastard that Michelangelo.
I (relatively) recently added the FILES table to INFORMATION_SCHEMA (check out the patch). This was so that we could provide an SQL interface to check how much free space their was in ndb disk data files. You can see how to use this in my post entitled INFORMATION_SCHEMA.FILES (querying disk usage from SQL). We’ll have stuff hitting the manual at some point soon.
So how is an INFORMATION_SCHEMA table implemented in MySQL? Well, the first thing to realise is that INFORMATION_SCHEMA (herein refered to as I_S) tables aren’t “real” tables – they are not created by the user (in fact, the user shouldn’t – or can’t – do DDL on the I_S database). Instead, the I_S database contains tables generated on-the-fly by the MySQL Server. Internally, we create MEMORY tables and convert them to MyISAM if they get too big and then run queries on them.
So, into the code. Bring up sql_show.cc and have a look. Specifically, scroll down to ST_SCHEMA_TABLE schema_tables[] and see that it’s the same as what SHOW TABLES gets you on the I_S database.
For adding the FILES table, you can see from my patch that we just add an item to this structure. (the hunk is below)
@@ -4655,6 +4726,8 @@
fill_schema_column_privileges, 0, 0, -1, -1, 0},
{"ENGINES", engines_fields_info, create_schema_table,
fill_schema_engines, make_old_format, 0, -1, -1, 0},
+  {"FILES", files_fields_info, create_schema_table,
+   fill_schema_files, 0, 0, -1, -1, 0},
   {"KEY_COLUMN_USAGE", key_column_usage_fields_info, create_schema_table,
get_all_tables, 0, get_schema_key_column_usage_record, 4, 5, 0},
{"OPEN_TABLES", open_tables_fields_info, create_schema_table,
As the comment indicates (oh my, a comment that’s correct!) you need to add an item to the enum in sql/table.h for the files table.
We’ll need to create the files_fields_info structure. This, as you guessed, describes the fields in the table. Above the schema_tables[] definition in sql_show.cc you can see the existing definitions for existing tables. Our (rather long) definition for FILES is:
ST_FIELD_INFO files_fields_info[]=
{
{"FILE_ID", 4, MYSQL_TYPE_LONG, 0, 0, 0},
{"FILE_NAME", NAME_LEN, MYSQL_TYPE_STRING, 0, 0, 0},
{"FILE_TYPE", 20, MYSQL_TYPE_STRING, 0, 0, 0},
{"TABLESPACE_NAME", NAME_LEN, MYSQL_TYPE_STRING, 0, 0, 0},
{"TABLE_CATALOG", NAME_LEN, MYSQL_TYPE_STRING, 0, 0, 0},
{"TABLE_SCHEMA", NAME_LEN, MYSQL_TYPE_STRING, 0, 0, 0},
{"TABLE_NAME", NAME_LEN, MYSQL_TYPE_STRING, 0, 0, 0},
{"LOGFILE_GROUP_NAME", NAME_LEN, MYSQL_TYPE_STRING, 0, 0, 0},
{"LOGFILE_GROUP_NUMBER", 4, MYSQL_TYPE_LONG, 0, 0, 0},
{"ENGINE", NAME_LEN, MYSQL_TYPE_STRING, 0, 0, 0},
{"FULLTEXT_KEYS", NAME_LEN, MYSQL_TYPE_STRING, 0, 0, 0},
{"DELETED_ROWS", 4, MYSQL_TYPE_LONG, 0, 0, 0},
{"UPDATE_COUNT", 4, MYSQL_TYPE_LONG, 0, 0, 0},
{"FREE_EXTENTS", 4, MYSQL_TYPE_LONG, 0, 0, 0},
{"TOTAL_EXTENTS", 4, MYSQL_TYPE_LONG, 0, 0, 0},
{"EXTENT_SIZE", 4, MYSQL_TYPE_LONG, 0, 0, 0},
{"INITIAL_SIZE", 8, MYSQL_TYPE_LONGLONG, 0, 0, 0},
{"MAXIMUM_SIZE", 8, MYSQL_TYPE_LONGLONG, 0, 0, 0},
{"AUTOEXTEND_SIZE", 8, MYSQL_TYPE_LONGLONG, 0, 0, 0},
{"CREATION_TIME", 0, MYSQL_TYPE_TIMESTAMP, 0, 0, 0},
{"LAST_UPDATE_TIME", 0, MYSQL_TYPE_TIMESTAMP, 0, 0, 0},
{"LAST_ACCESS_TIME", 0, MYSQL_TYPE_TIMESTAMP, 0, 0, 0},
{"RECOVER_TIME", 4, MYSQL_TYPE_LONG, 0, 0, 0},
{"TRANSACTION_COUNTER", 4, MYSQL_TYPE_LONG, 0, 0, 0},
{"VERSION", 21 , MYSQL_TYPE_LONG, 0, 1, "Version"},
{"ROW_FORMAT", 10, MYSQL_TYPE_STRING, 0, 1, "Row_format"},
{"TABLE_ROWS", 21 , MYSQL_TYPE_LONG, 0, 1, "Rows"},
{"AVG_ROW_LENGTH", 21 , MYSQL_TYPE_LONG, 0, 1, "Avg_row_length"},
{"DATA_LENGTH", 21 , MYSQL_TYPE_LONG, 0, 1, "Data_length"},
{"MAX_DATA_LENGTH", 21 , MYSQL_TYPE_LONG, 0, 1, "Max_data_length"},
{"INDEX_LENGTH", 21 , MYSQL_TYPE_LONG, 0, 1, "Index_length"},
{"DATA_FREE", 21 , MYSQL_TYPE_LONG, 0, 1, "Data_free"},
{"CREATE_TIME", 0, MYSQL_TYPE_TIMESTAMP, 0, 1, "Create_time"},
{"UPDATE_TIME", 0, MYSQL_TYPE_TIMESTAMP, 0, 1, "Update_time"},
{"CHECK_TIME", 0, MYSQL_TYPE_TIMESTAMP, 0, 1, "Check_time"},
{"CHECKSUM", 21 , MYSQL_TYPE_LONG, 0, 1, "Checksum"},
{"STATUS", 20, MYSQL_TYPE_STRING, 0, 0, 0},
{"EXTRA", 255, MYSQL_TYPE_STRING, 0, 0, 0},
{0, 0, MYSQL_TYPE_STRING, 0, 0, 0}
};
So now we’ve added a table to I_S and defined the table. The universal create_schema_table will take care of creating the table for us – we just need to write the function to fill the table now!
If we want to test where we’re up to now, an empty function will do. For example, you could add something like this to sql_show.cc:
int fill_schema_files(THD *thd, TABLE_LIST *tables, COND *cond)
{
return 0;
}
Now you can build, run and test, but the real function is a lot more interesting. Since each storage engine can have its own files, we create a handlerton (the data structure for a table handler – see handler.h) call for the handler to fill out its bit of the FILES table.
struct run_hton_fill_schema_files_args
{
TABLE_LIST *tables;
COND *cond;
};

static my_bool run_hton_fill_schema_files(THD *thd, st_plugin_int *plugin,
void *arg)
{
struct run_hton_fill_schema_files_args *args=
(run_hton_fill_schema_files_args *) arg;
handlerton *hton= (handlerton *) plugin->plugin->info;
if(hton->fill_files_table)
hton->fill_files_table(thd, args->tables, args->cond);
return false;
}

int fill_schema_files(THD *thd, TABLE_LIST *tables, COND *cond)
{
int i;
TABLE *table= tables->table;
DBUG_ENTER("fill_schema_files");

struct run_hton_fill_schema_files_args args;
args.tables= tables;
args.cond= cond;

plugin_foreach(thd, run_hton_fill_schema_files,
MYSQL_STORAGE_ENGINE_PLUGIN, &args);

DBUG_RETURN(0);
}
So, the fill_schema_files() function is what the I_S code calls. Since in MySQL 5.1 we have a much improved plugin infrastructure, we use the plugin_foreach function which iterates over the loaded storage engines in a safe way. For each storage engine, we end up calling run_hton_fill_schema_files with the args structure as a parameter. As you can see, if the handlerton has a fill_files_table function, we call it.
Now that we’re here, we need to implement fill_files_table for some table handlers. For storage engines we’re not going to implement it, we need to make sure they set it to NULL (there’s a bunch of this going on in the aforementioned patch).
Since for the NDB table handler (ha_ndbcluster.cc) we have a lovely sane init function (ndbcluster_init) it’s much easier to support new handlerton calls:
h.fill_files_table= ndbcluster_fill_files_table;
That’s all that’s needed (apart from the implementation of course :)
So, what does the implementation look like? It’s easy to see how it works from the source, so I won’t go into details here. Basically, we fill out a row using data retreived via the NDBAPI and call schema_table_store_record(). How you construct the function for your storage engine may be quite different, enjoy!
One useful query that jeb is using in some of the tests is:
SELECT FILE_NAME, (TOTAL_EXTENTS * EXTENT_SIZE) AS 'Total Extent Size',
(FREE_EXTENTS * EXTENT_SIZE) AS 'Total Free In Bytes',
(((FREE_EXTENTS * EXTENT_SIZE)*100)/(TOTAL_EXTENTS * EXTENT_SIZE))
AS '% Free Space' FROM INFORMATION_SCHEMA.FILES
+ WHERE ENGINE="ndbcluster" and FILE_TYPE = 'DATAFILE';
You may want to CREATE VIEW blah AS … for this as it could be a useful query to run regularly
AUSTRALIA PRESS: Telstra To Charge More For Fixed Lines
great – I get to pay more for a service I DON’T WANT! I just want internet, not a phone line (which I aparrently have to have to get ADSL).
Howard: What the blogs are saying
I’m not a Howard fan. I think he plays politics very well – possibly better than anyone in the country (and is certainly a world contender) and I’d love to have him on my side on issues I care about. I also
I also think he’s wrong on a bunch of things (or not paying the right kind of attention to them). Some of these I think it’s possible to work on, but others are just fundamental differences.
(hrrm… some major ones there. I am quite happy though that (at least in the past) he has been active in upholding the right to choose on abortion and not giving into a certain health minister who wants to impose his moral view on the country.
This isn’t to say that there’s a feasible opposition. The Australian Labor party is a joke. Total discrace. I’m feeling like I could say that I feel that the Greens have a higher chance of winning government in the next two elections than the ALP.
Way to get depressed about the political situation in .au
Frank Mash askes MySQL 5.1 still in beta? Well, yes. Otherwise known as “just entered beta” :)
As for when it’ll be GA, the answer is, as always “when it’s ready.” If you look at 5.0 – it went beta on 23rh March 2005 and declared production on 19th October.
I would hope a similar timeframe for 5.1
My advice would be to run out of cron today, and when you’re comfortable with deploying 5.1, use events in it. Of course, test on both.

Finger currently bandaged like the above. On monday night i sliced a bit of my finger off. Not too much, it’ll grow back.
downside of having an unco moment with a good sharp knife.
congratulations to chris and kelly.
Best wishes to Leon and family for a quick, speedy and complete recovery.
Just got back from going to see Augie March play at the Prince.
Went with Mike: 
They played The Keepa: 

Another funky track:
And, of course, There Is No Such Place: 

Guess you're happy with that answer. To fix the mirroring, he needs to create the non-zero sizes (contents don't matter) in the  ARCHIVE/=meta-info/http-blows file.
Then he needs to run archive-fixup on the name of the mirror
So, for example, if he can ssh to where the mirror is, he can echo "yeah" > HERE/IS/MY/MIRROR/=meta-info/http-blows, then back on the machine that has the original source, run archive-fixup ARCHIVE-MIRROR
Thank you interweb, you fixed it.
I’m currently in the process of trying out Tailor to convert the CVS repository that stores the revision history of my website to bzr.
I’ve been meaning to try bzr again for ages, and here’s the excuse. I’m going to see if this is going to work well for me.
Basically, what I do is I hack things locally, test, then rsync to web host. I blog using the live webhost site and rsync back (with a mysqldump before the rsync).
The only thing I’m really noticing at the moment is that the import speed seems to be fairly slow. If I were doing this on a mysql tree, I’d probably just go to bed. or wait until next week.
Thanks to James for his handy little HOWTO on doing this.
xine --keymap=lirc
Is a useful command to run. I redirected it to a file and appended an edited copy to my existing lircrc for mythtv.
I used to run irxevent, but am now using mythtv’s builtin support. I had to symlink ~/.lircrc to ~/.mythtv/lircrc
I have a Winfast TV Deluxe 2000 (or some such thing). The lircrc file I’m using now is lircrc
Upgraded the mythtv box to 0.19 today. Quite neat. Even have switched over to using the built in lirc support. This should make it easy to get DVDs getting played through the myth box without using the keyboard to control xine.
looking forward to iT!
(stolen out of Mikael’s post to the cluster list – http://lists.mysql.com/cluster/2396)
Both REDO and UNDO logs are stored in buffers but are sent after a while to disk.
For REDO the disk write happens when 256 kByte of buffer is filled up or when a GCP requests synching the data (the 256 kByte write is without synch
but every 4 MByte gets synched even without GCP occurring.
For UNDO similar algorithm that write when 256 kByte of buffer is filled, synch after 4 MByte or when the local checkpoint is completed.
I wonder if we should be tuning more? I honestly don’t know the answer to this – but I don’t think it’s a limiting factor at the moment :)
up to 3 copies of data (3*DataMemory)
+ 64MB * NoOfFragLogFiles (default=8)
+ UNDO log (dependent on update speed)
For example:
DataMemory=1024MB
idea on disk usage= 1024*3 + 64 * 8 =Â 3584MB + UNDO log
It’s very tempting to have a “SHOW ESTIMATES” command in the management client/server that performs all these equations (and the answers). I bet Professional Services would love me :)
On an internal list, a thread switched over to breifly mentioning the film Munich which incidently, I saw a few weeks ago just after linux.conf.au and really enjoyed.
I thought it was really well done and a good film. I really recommend going to see it – it’s a good cinematic experience. Possibly don’t see it if you’re feeling really sad though – not exactly a happy film. Eric Bana and Geoffrey Rush are superb in this film (both Aussies too!).
I found it to be more about his journey than anything else and enjoyed it as it was a personal story.
Oh, and why haven’t Margaret and David reviewed it yet? I would love to know what they thought. It’s not often I see a film before I’ve seen them review it :)
Slashdot | Olympic Medalist was Spyware King
They ask “shouldn’t they be disqualified for behaviour like that”. Well, personally I think it should carry jail time. Possibly public flogging. In fact, just have somebody poke them with a sharp stick every minute of every day for 10 years and occationally have loud things scream in their ears. Also, make their phone ring with telemarketers and their mailbox fill up with offers for stuff they don’t need or want.
I hate spammers. Rot in $bad_place you parasites.
I really have no time for spammers.
Okay, I cheated – I used one of the bottled curry pastes. I really shouldn’t have – it’s not that hard to do it yourself. But, I was feeling *really* lazy.
So, ingredients were:
saute the onions, throw in the tofu and cook . add the can of tomatoes and curry paste – in fact, add everything else.
Cook until good and warm all the way through. The tofu I used has a habit of crumbling – didn’t harm the taste though!
This was really yummy. Ate it last night as leftovers and made it the night before. Wish I had more for tonight. Delicious!
EnterpriseDB : Open source based relational database, PostgreSQL based database management software
Oh, that’s right – it’s a proprietary database! “Based on PostgreSQL” – well, good for them – they got a bunch of stuff for free[1]. But without a commitment to having the source out there for every release (or even the development tree) how committed are they really?
How can anybody tell if their improvements are good and well written or just utter hacks that would make you loose your lunch? (not dissing their programmers here, just pointing out that you cannot know).
Meanwhile, over here at MySQL, every single time that a developer types bk commit, an email is sent (with the content of the patch) to a public list[2]. Also, the development trees are out there, as is the source to every release in a tarball. So you can get the complete revision history of the MySQL server.[3]
That’s called committment to freedom!
[1] I understand they do pump some stuff back into PostgreSQL, but it’s still a fork with non-public bits! This also isn’t a diss on PostgreSQL.
[2] Yes, people do actually read this. I have (personally) gotten replies from people out there in the big wide world about commits I’ve made to the source tree.
[3] We’re not perfect by any means – but IMHO we’re pretty good and there’s lots of people totally committed to making sure we get better.
Oracle has 50,000 employees. Thats 50,000 people waking up each day to work on Oracle products, and those 50,000 get paid by Oracle each day. We have 50,000 people download our software everyday and work to make it better. But we dont pay them. Which model would you rather have?
A quote from our CEO Marten Mickos in “Oracle’s New Enemy” over at forbes.com.
It is pretty neat to have your work seen by that many people each day.